SteadyVane
Daily brief · November 15, 2026

How to rethink your Claude Code setup for the newest Claude models

3 items that moved, with the numbers. Measured by SteadyVane, fact-checked, and graded before publishing.

How to rethink your Claude Code setup for the newest Claude models

496,052 → 579,050views of the video in 24 h · 210 commentsabout 19× the typical pace of other tracked AI-tool videos

Lydia Hallie, a Member of Technical Staff on Anthropic's Claude Code team, gave a talk at the AI Engineer Code Summit. Its premise is that a setup built around an older model can become an obstacle for a newer one. It covers what is still worth keeping and auto mode, which Hallie describes as a classifier that approves actions it considers safe and blocks uncertain ones.

A video of the talk went up 82,998 views in 24 hours, from 496,052 to 579,050 - about 19 times the typical pace of other AI-tool videos SteadyVane tracks on YouTube. It has 6,831 likes and 210 comments, about three days after it was published.

Why it matters: If you built your Claude Code setup a while ago, the talk is a prompt to check whether it still fits the model you run now. Anthropic's docs say interactive sessions now start in auto mode.

A setup is worth reviewing when the model underneath it changes.

How to scale AI coding agents with architecture, lint rules and layered verification

70,264 → 214,640views of the video in 12 h · 300 commentsabout 79× the typical pace of other tracked AI-tool videos

Lauren Tan, a Principal Engineer at SpaceXSI, gave a talk at the AI Engineer Code summit on keeping AI coding agents reliable. Her 'trust pyramid' puts codebase design and static analysis ahead of prose instructions. One example is explicit directories with lint rules that forbid imports across the wrong boundary.

A video of the talk went up 144,376 views in 12 hours, from 70,264 to 214,640 - about 79 times the typical pace of other AI-tool videos SteadyVane tracks on YouTube. It has 4,901 likes and 300 comments, about 17 hours after it was published.

Why it matters: It shifts the question from writing better prompts to shaping the codebase so that bad changes are hard to make. The video description states the Grok Bot team made 11,000 pull requests in one month with a revert rate around 0.5%.

Constraints in code do not depend on an agent reading your instructions correctly.

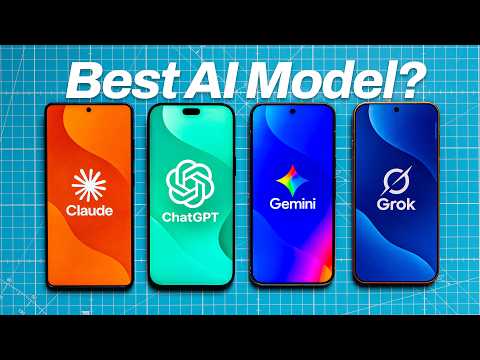
Free Claude, ChatGPT, Gemini and Grok tested head to head in their phone apps

16,555 → 31,622views of a video about it in 2.3 days · 48 comments

A video from the channel Techmo runs the free models in each native Android and iOS app side by side: Claude's Sonnet 5.5, ChatGPT's GPT-6 (Luna), Gemini on Auto and Grok on Fast. The fact-check confirmed these are the models the free apps actually run.

A video about it went from 16,555 to 31,622 views in 56 hours, and has 314 likes and 48 comments about four days after it was published.

Why it matters: Which model sits behind a free app is not always clear: free Gemini users no longer have a model picker, xAI does not name the model behind free Grok, and OpenAI's Help Center names a different Luna model than its GPT-6 announcement. A test of what each free app runs is useful if you rely on a free tier.

Before judging a free chatbot, check which model is actually behind it.

All briefs · What is rising now